LLM Agents

Persistent Memory in Multi-Agent LLM Inference: What It Costs, What It Buys, and When You Can Tell

Agent decomposition bounds peak KV cache 2.5× below single-pass and RAG baselines; the persistent memory tier such systems are usually paired with costs cache and buys no …

avatar
Hochan Son
•
Edge LLM Inference via Chain of Agents featured image

Edge LLM Inference via Chain of Agents

Memory-efficient local LLM inference using a Chain-of-Agents approach.

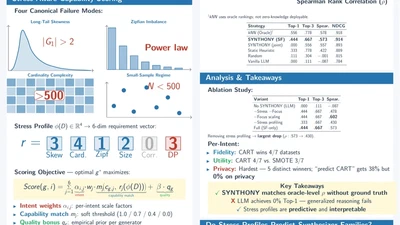
SYNTHONY: A Stress-Aware, Intent-Conditioned Agent for Deep Tabular Generative Models Selection featured image

SYNTHONY: A Stress-Aware, Intent-Conditioned Agent for Deep Tabular Generative Models Selection

Stress-aware, intent-conditioned agent that recommends the best-fit tabular generative model for a dataset instead of defaulting to one architecture.

avatar
Hochan Son
•
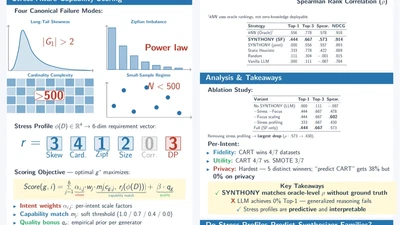
Synthony featured image

Synthony

Stress-aware, intent-conditioned agent for generative model selection.